The Context Lakehouse
The speed of DuckDB at any scale, with dedicated compute for every user and every agent
Built for agent-scale workloads
Largest single table tested
- 100Brows
Largest lake measured
- 500TB
Ingestion throughput measured
- 100Kevents/s
A flexible compute model
Every query runs on a dedicated DuckDB Worker that starts on demand and scales to zero when idle. Hot data sits on local NVMe. Durable data stays in object storage you choose.
 Serverless compute
- AWS
- Google CloudComing soon
- AzureComing soon
- EU sovereign deployment
- Bring your own compute
Your tables, in open formats. Fully managed.
Store new data in DuckLake or Apache Iceberg tables, written as open Parquet files. Altertable runs the catalog, file layout, and query path, with ACID transactions, partitioning, and sort orders on every table.
Automatic compaction
Altertable merges small files and rewrites them in sort order in the background, so scans stay fast as tables grow. No maintenance jobs to schedule.
Realtime reads
New rows are queryable as soon as they are committed. Hot files stay on local NVMe, so dashboards, apps, and agents read fresh data in under a second.
Streaming ingestion
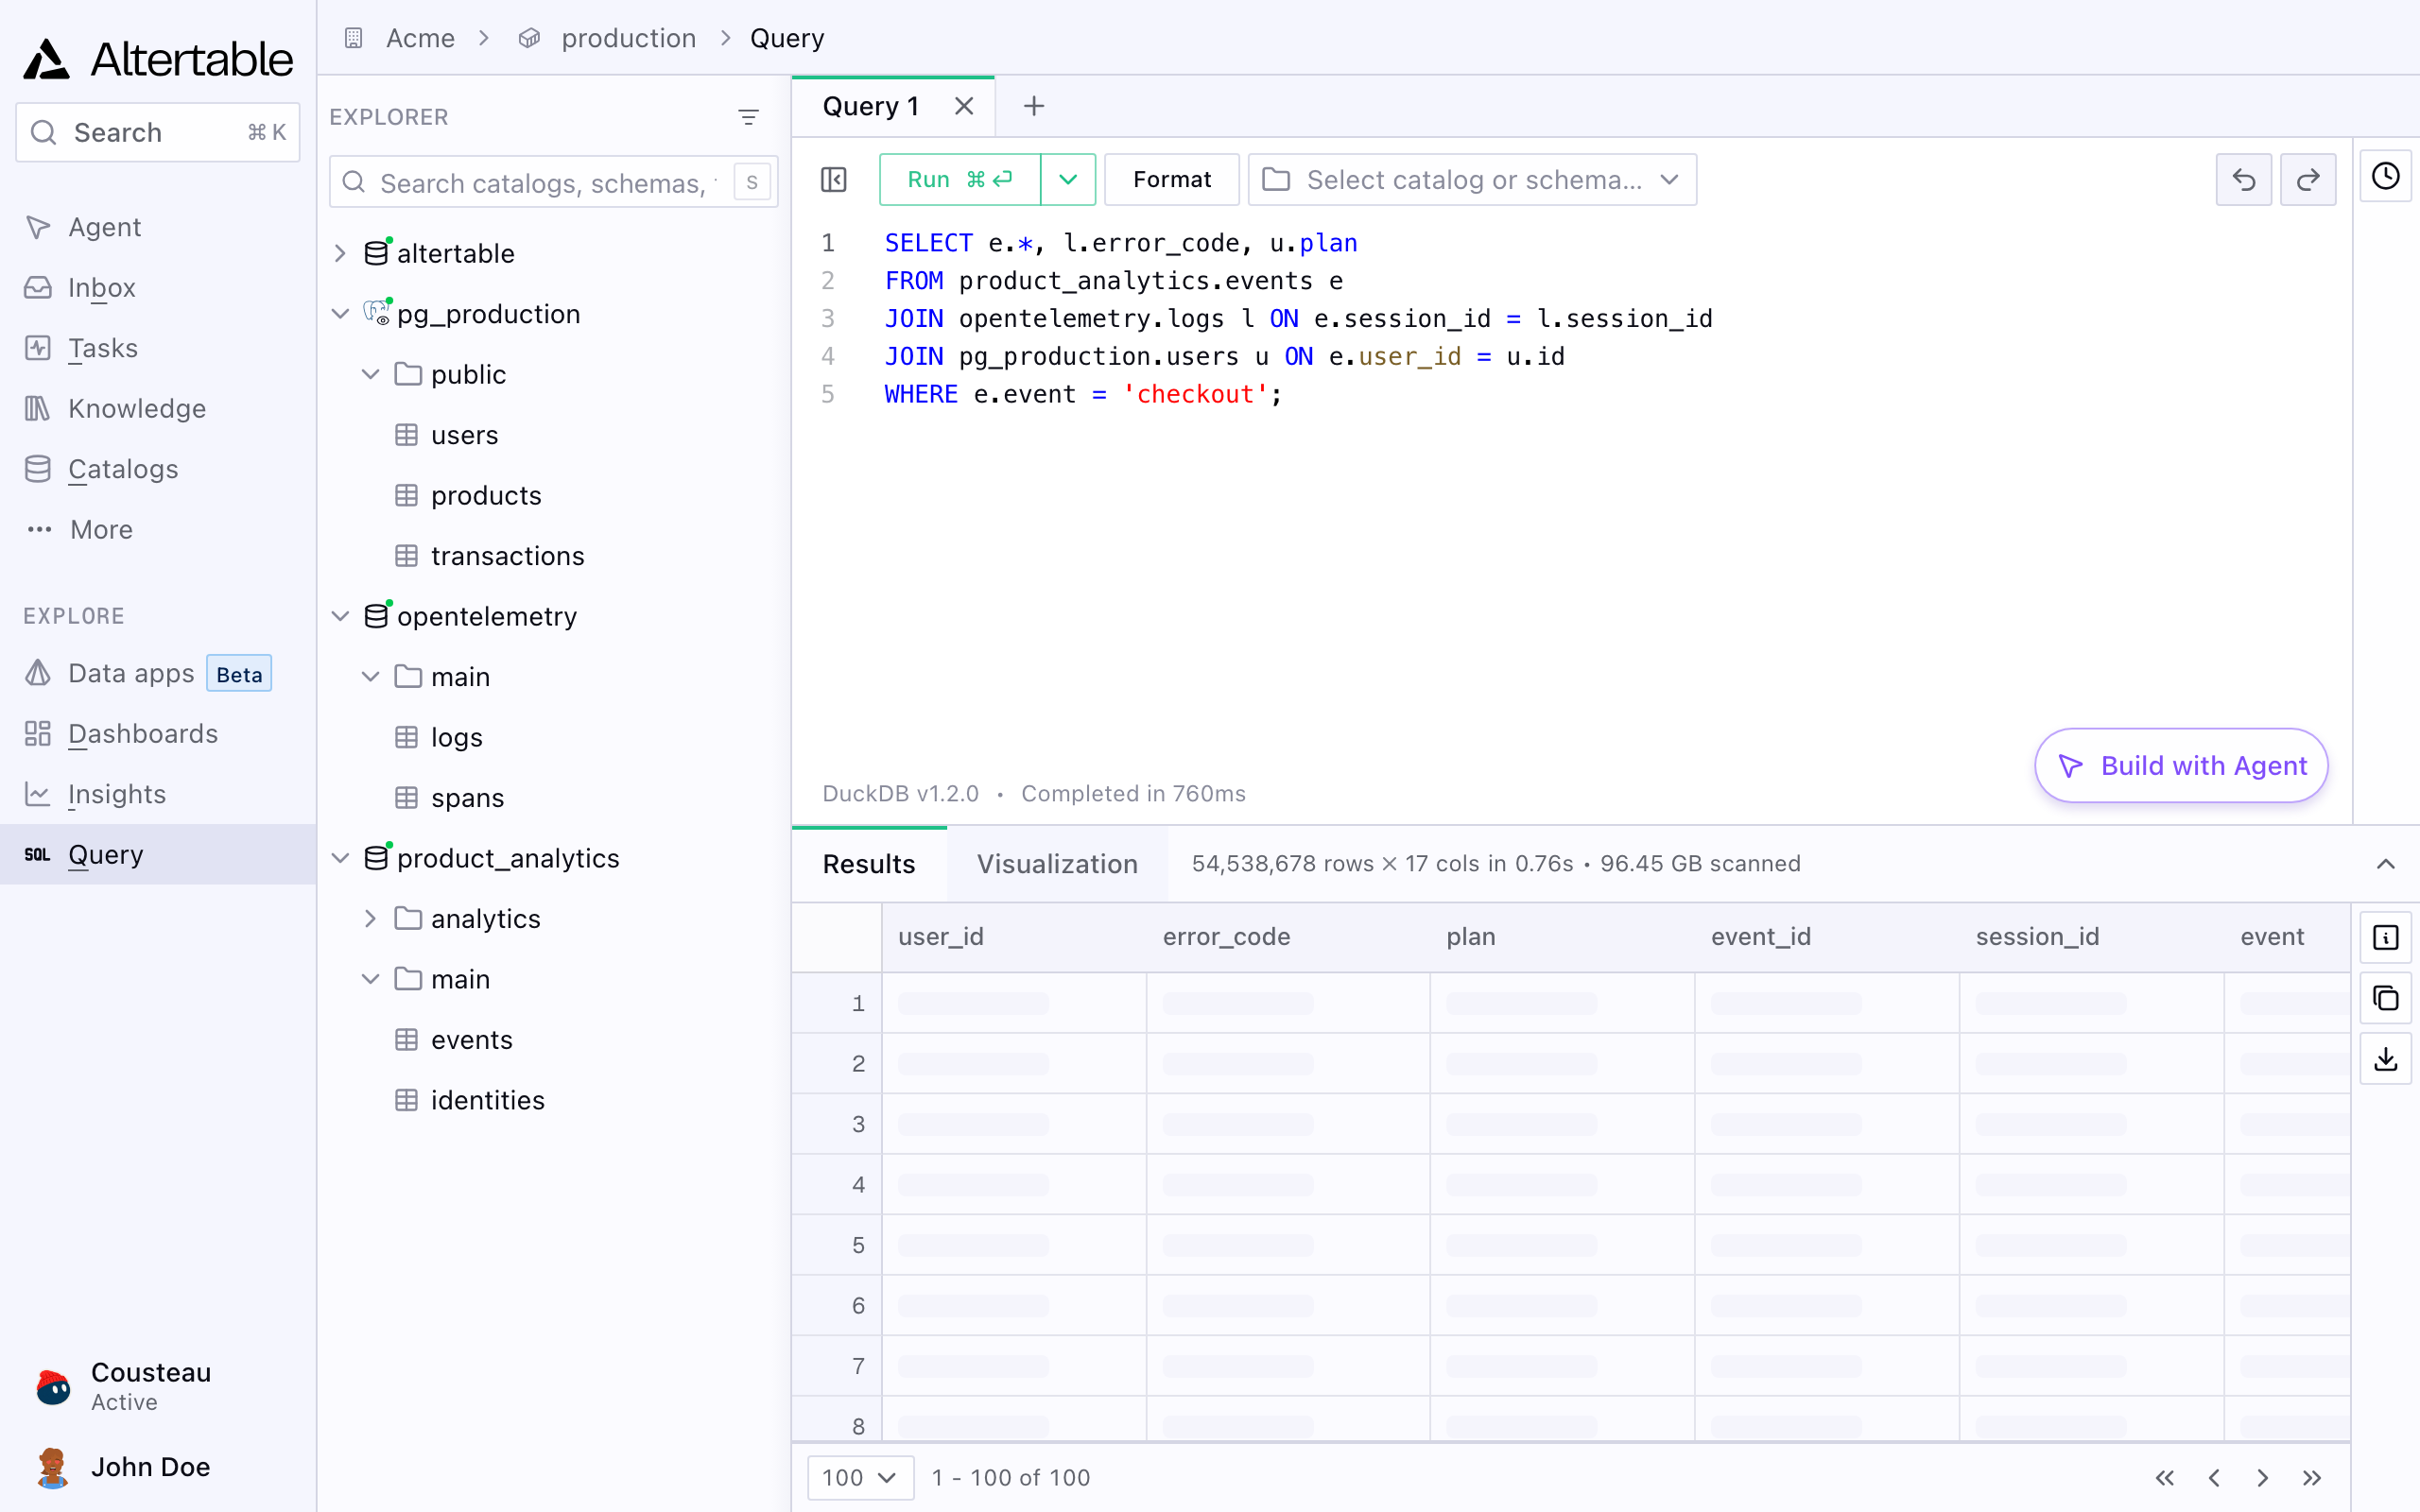
Stream product events through Product Analytics and logs and traces through OpenTelemetry. Query incoming data in realtime alongside your business data.
Time travel
Query any table as it was at a past snapshot or timestamp. Audit changes, debug a bad load, or compare before and after a release.
Full-text search
Index text columns and search them by word, phrase, or fuzzy match, straight from SQL. No separate search cluster to keep in sync.
Event analytics in SQL
Build sessions, user journeys, and funnels with SESSIONIZE, JOURNEYS, and MATCH_RECOGNIZE. No stacks of self-joins and window functions.
Partitioning, sorted tables, change data feeds, views, and more.
Explore lakehouse featuresFaster and cheaper than the incumbents
Altertable outperforms Snowflake and BigQuery on industry-standard analytics workloads.
At a fraction of the cost.
Query Time
Average TPCH Benchmark (sf=100) results - lower is better
Monthly Cost
Estimation - lower is better
The lakehouse every builder and agent can use
Ingest data, query it from your tools, or hand it to AI agents,
all through the same governed lakehouse APIs.
Append rows or upload files over a lightweight HTTPS API.
curl -X POST "https://api.altertable.ai/append?catalog=my_catalog&schema=main&table=events" \-H "Authorization: Basic $ALTERTABLE_BASIC_AUTH_TOKEN" \-d '{"timestamp":"2026-01-01","event":"click","value":42}'
More ingest paths in docs.
Before your first query.
A few answers.
DuckDB, compute sizes, storage, and the tools you already run.
What does Altertable add to DuckDB?
Altertable adds managed storage, dedicated compute, and governed access to DuckDB, so your team, applications, and AI agents can query the same data. It also includes tailored extensions for full-text and semantic search, a semantic layer, and event and pattern queries.
What sizes of compute workers are available?
From XS (2 Compute Units) to 4XL (128 Compute Units). Pick a size for each query, or let Altertable choose with AUTO. Workers start on demand, give every user and agent their own compute, and scale to zero when idle.
Where does my data live?
In open Parquet files on object storage, in a managed bucket or your own. Data can also stay in your existing database or warehouse, and Altertable queries it in place. No proprietary format, no lock-in.
Can I keep using my existing tools?
Yes. Altertable speaks the protocols your stack already uses. Connect BI tools, notebooks, dbt, and any Postgres or Arrow Flight SQL client to the same data, and give agents governed access through MCP.
Run analytics, apps, and agents on one lakehouse
DuckDB workers on open formats, federated SQL across your existing systems,
and an MCP server for agents — at flat monthly pricing.